How I Set Up AI Agents for Complex, Long-Running Work
I spend a lot less time watching the agent now
When I wrote about AI-directed development, my default was close supervision. Auto-writes off, approve each change, review in small chunks, loosen the reins once I trusted the shape of the solution. That worked, and the core idea still holds: shape decisions early, before they harden into code.
But the way I apply it has changed a lot. These days I'll hand an agent a large, complex feature and let it work for long stretches, sometimes hours, and it stops mostly when it hits a decision that genuinely needs me or something it didn't expect. I'm not watching every file change any more.
That isn't because I decided to trust the same tools more. Three things changed underneath me:
- The models got better. In my experience they carry complex work forward far more reliably than they did even six months ago. They hold a plan together across a long session, recover from their own mistakes more often, and are better at noticing when something doesn't add up.
- My tools evolved. I've been building AgentLink, and it now has an Approve for Me mode. Routine actions run under the rules I've already set, and anything riskier goes to a Guardian reviewer that judges it against what I actually asked for. My Prompt and Forbidden rules still apply, and protected or uncertain actions still come back to me. So I'm not clicking approve on every test run, but I haven't switched the safeguards off either.
- I give better guidance up front. Research, skills, project instructions, and a clear plan mean the agent has far fewer decisions to guess at.
The goal isn't a record-length run or an agent that never asks a question. It's longer stretches of useful work with fewer preventable wrong turns. I still own the product decisions and I still own what ships.
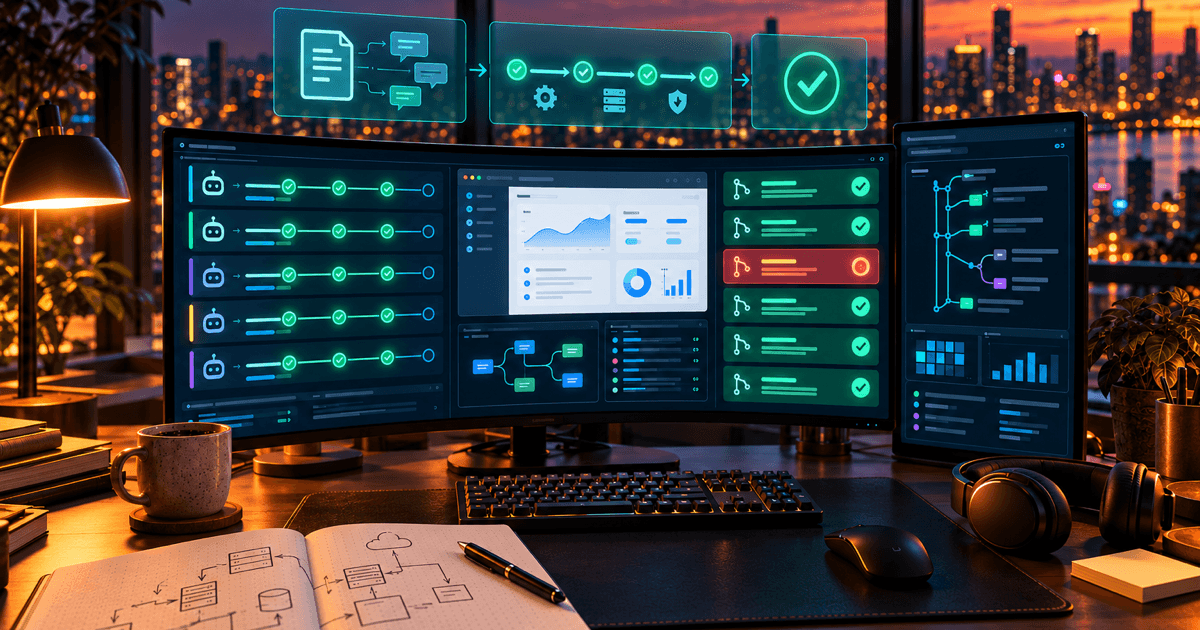
The rest of this post is how I set that up. Here's the overall shape:
The session starts before the big prompt
The most useful work for a long session often happens before I ask the agent to build anything. If I already know a big task is coming, I ask myself what would make it easier to get right.
Sometimes that's research. If the feature leans on a third-party API or platform I don't know well, I'll run a separate session to read the official docs and write up what's possible, what isn't, and what's still unverified. That way the build session starts from facts rather than whatever the model half-remembers.
Sometimes it's tooling. Can the agent actually run the thing it's building? Can it start the local stack, run the relevant tests, open a browser against it? An agent that can verify its own work catches a whole class of problems without me. An agent that can only write code and hope tends to hand those problems to me at the end.
Sometimes it's a skill or a project instruction: a convention the agent keeps getting wrong, a review checklist, the way a team wants PRs written. In Gram, the repo I work in at Speakeasy, our guidance for writing skills goes a step further. You check that a skill actually changes behaviour by having a fresh agent do a real task with only that skill to go on, rather than assuming a well-written document will work. I like that approach a lot, because guidance that reads well and guidance that works aren't always the same thing.
I don't build a new tool or skill for every task, though. The point is targeted preparation where it pays off, not a ritual.
Make the plan survive disagreement
For anything substantial, I have a frontier model help me write a plan or RFC before any code gets written. Then I try to break it.
I get the plan adversarially reviewed, usually more than once. Inside AgentLink I can route a review to a model from a different provider as part of the workflow. I also open completely separate sessions with different models and deliberately different context, so the reviewer isn't just agreeing with reasoning it's already been primed with. A model reviewing its own plan in the same context tends to polish the explanation rather than challenge the assumptions.
A good review checks the plan against the actual code and source material. Does this API really support that? Does this permission model actually hold? What happens on teardown, or when a credential expires? Findings still need judgement, though. I don't accept everything a reviewer says, and I don't treat it as a vote between models. Some findings are real, some are wrong, and some are true but not worth the complexity.
My own review is where SuperMarkdown comes in. It's a VS Code Markdown preview I built because reviewing long plans was clunky. I read the rendered document, diagrams included, make inline edits where I just want to fix something, and leave comments where I want the agent to rethink something, all without stopping my reading flow. The comments are saved where an agent can read and address them. It sounds like a small thing, but removing that friction means I actually do the careful review instead of skimming.
I don't have a fixed number of review rounds. I stop when the material objections are resolved and further review is mostly producing polish. Endless review is its own failure mode.
Give the agent a clear working agreement
When the plan is solid, the brief I give the build session reads less like a prompt and more like a working agreement. It usually covers:
- The outcome, and what success looks like in practice
- Non-goals, so it doesn't helpfully expand the scope
- Constraints that matter: security boundaries, compatibility, things it must not touch
- References: the plan, research docs, relevant skills
- The first thing I want to see, which is usually a slice I can try
- How the work should split into reviewable pieces
- How to validate it, and what counts as done
- When to stop and ask
That last one is the one that makes long sessions work. Routine implementation choices should just proceed. I don't want a question about naming a helper. But unresolved product decisions, evidence that contradicts the plan, a scope change with real risk, or anything outside what I've granted it should come back to me, with the trade-off explained and a recommendation.
Instructions aren't a security boundary, though. "Don't touch production" in a prompt is a request. Sandboxing, approval rules, and narrowly scoped credentials are what actually enforce it.
For really long work, I also ask the agent to keep the plan and key decisions written down and up to date. Sessions get condensed or resumed, and you don't want a settled decision quietly reopening itself three hours in.
Get something I can react to early
The thing that's improved my results most is getting something in my hands early, before the feature is finished.
Ideally that's a vertical slice: a rough version that works end to end, that I can click through and play with. Five minutes using it tells me more than an hour reading the code, and it's when I discover the flow is wrong, or a setting is in the wrong place, or the thing I asked for isn't quite the thing I wanted.
For UI work, I'll often ask for rendered concepts even earlier: a few different directions I can look at and react to before anything gets built. Concepts are great for testing ideas cheaply, but they're not evidence that anything works. I keep that distinction clear.
I also get the agent to make its work inspectable. Playwright lets it drive the app in a real browser and screenshot the states that matter: loading, empty, error, long values, narrow screens. Image and video tools can turn that into something I can review quickly. Gram's frontend guidance even has a fresh agent critique screenshots without knowing how the code works, which catches the kind of visual problems the author is blind to.
None of this replaces tests. A demo shows me behaviour, tests protect it. And not every change needs an elaborate demo pipeline. A backend refactor might just need a clear test plan.
Keep steering possible, and make delivery reviewable
Even with good preparation, agents drift. The difference now is that I can correct course while the work is happening, instead of discovering the problem in a giant PR at the end.
AgentLink lets me steer within a session: interject at the next tool break, redirect, or answer a question without restarting. Combined with Approve for Me, the split is pretty clean. Routine tool approvals are handled by my rules and Guardian. Product and architectural decisions come to me. I'm not babysitting, but I'm reachable when it matters.
The other half is how the work arrives. I ask the agent to break a big feature into coherent, reviewable pieces rather than one enormous change.
The Tailscale integration I built for Gram is a good example. It lets Gram-hosted MCP servers be reached privately over a customer's own tailnet instead of the public internet. That's a feature that touches almost everything: the database, Kubernetes provisioning through the Tailscale operator, permission boundaries, background workers, and the dashboard. It landed as a series of pieces, each with a clear job and explicit notes about what was deliberately out of scope. Security-sensitive pieces got an independent security review, and findings were fixed before the feature was ever activated. The dashboard work was checked in a browser at desktop and mobile widths.
Merging code and turning the feature on were separate decisions. The pieces shipped behind rollout gates and stayed dormant until the infrastructure was validated. That's what made it safe to review and merge incrementally: no single piece had to be "the whole feature, working in production" to be worth merging.
A separate PR isn't automatically a small diff or a usable slice, mind you. Some of those pieces were substantial. The point is that each one could be reviewed on its own terms by someone who hadn't followed the session.
Passing tests doesn't mean it solved the right problem
Here's an example from follow-up work on that same feature where my judgement mattered more than any check.
A customer reported that their MCP servers showed a warning saying private network access was no longer enabled. I asked an agent to fix what looked like a copy issue. It found the warning, rewrote it to be clearer, ran the tests and type check, and everything passed. It was a perfectly reasonable fix for the task I'd described.
It was also wrong. Looking at it again, I realised the customer's private access was clearly working. The problem wasn't the wording, it was that the warning was appearing at all. With that steer, the agent found the real cause: the dashboard required both a staff-enabled feature and a particular plan, while the server only checked the feature. So an organisation that changed plans kept working traffic but saw a false warning and locked settings. The fix moved from the copy to the access logic.
Then an automated reviewer pointed out that one of the agent's new tests could never fail, because it set up a state where the condition it was checking couldn't occur. That got fixed too.
Two lessons. First, the agent solved the problem I framed, and the framing was wrong. Tests can't catch that. Second, a passing test isn't the same as a meaningful one. Neither the agent nor I caught every mistake early in this case, and that's fine. What matters is that the loop caught them before they shipped.
A brief worth reusing
Here's the shape of the brief I start from for a long session. It's not a magic prompt, and it doesn't replace good project guidance, but it covers the things I've learnt to be explicit about:
## Goal
What we're building and why. What success looks like in practice.

## Non-goals
What's explicitly out of scope.

## Constraints
Security, compatibility, and anything you must not touch.

## References
Plan/RFC, research notes, relevant skills and conventions.

## First milestone
The earliest slice or concept I can try and give feedback on.

## Delivery
How to split the work into reviewable PRs. Each PR description should
explain its scope, what's deferred, and how to verify it.

## Validation
Tests and checks to run. Browser or demo evidence where behaviour matters.

## When to stop and ask
Unresolved product decisions, evidence that contradicts the plan, risky
scope changes, or anything outside granted permissions. Explain the
trade-off and recommend an option. Otherwise, keep going.

## Keep notes
Keep the plan and key decisions up to date as you go.
And the checklist I run through before kicking one off:
- Does the agent have the research it needs, or is it going to guess?
- Can it run and verify what it's building?
- Has the plan been challenged by a reviewer with fresh context?
- Is it clear what it should decide and what it should bring to me?
- Will I get something to try early?
- Will the work arrive in pieces someone else can review?
The bottom line
Long-running agent sessions work for me now because the models and tools have improved, and because I put the effort in before and around the session rather than hovering over it. Prepare what the agent needs, make the plan survive disagreement, agree when it should ask, get something playable early, and keep the ability to steer.
Less oversight doesn't come from trusting the agent more. It comes from leaving it less to guess.
If you're trying this on bigger tasks, pick one thing from the checklist you're not doing yet. For most people I suspect it's the early playable slice. It's the fastest way I know to find out you're building the wrong thing while it's still cheap to change.
Have thoughts on this? Join the conversation on LinkedIn.
Join the Discussion
Have thoughts on this post? I'd love to hear from you! Join the conversation on LinkedIn where we can discuss, share insights, and connect.
Comment on LinkedIn
Tristan Cartledge
AI enablement consultant and fractional CTO. Founding and Principal Engineer at Speakeasy, building the AI Control Plane, and creator of AgentLink. Based in Cairns, Australia, working with teams worldwide.
Enjoy the content? Support my writing and projects.